By Ravish Handoo
Microsoft’s global outage raises serious questions about the risks of AI-assisted software development and the growing dependence of modern society on automated technology.
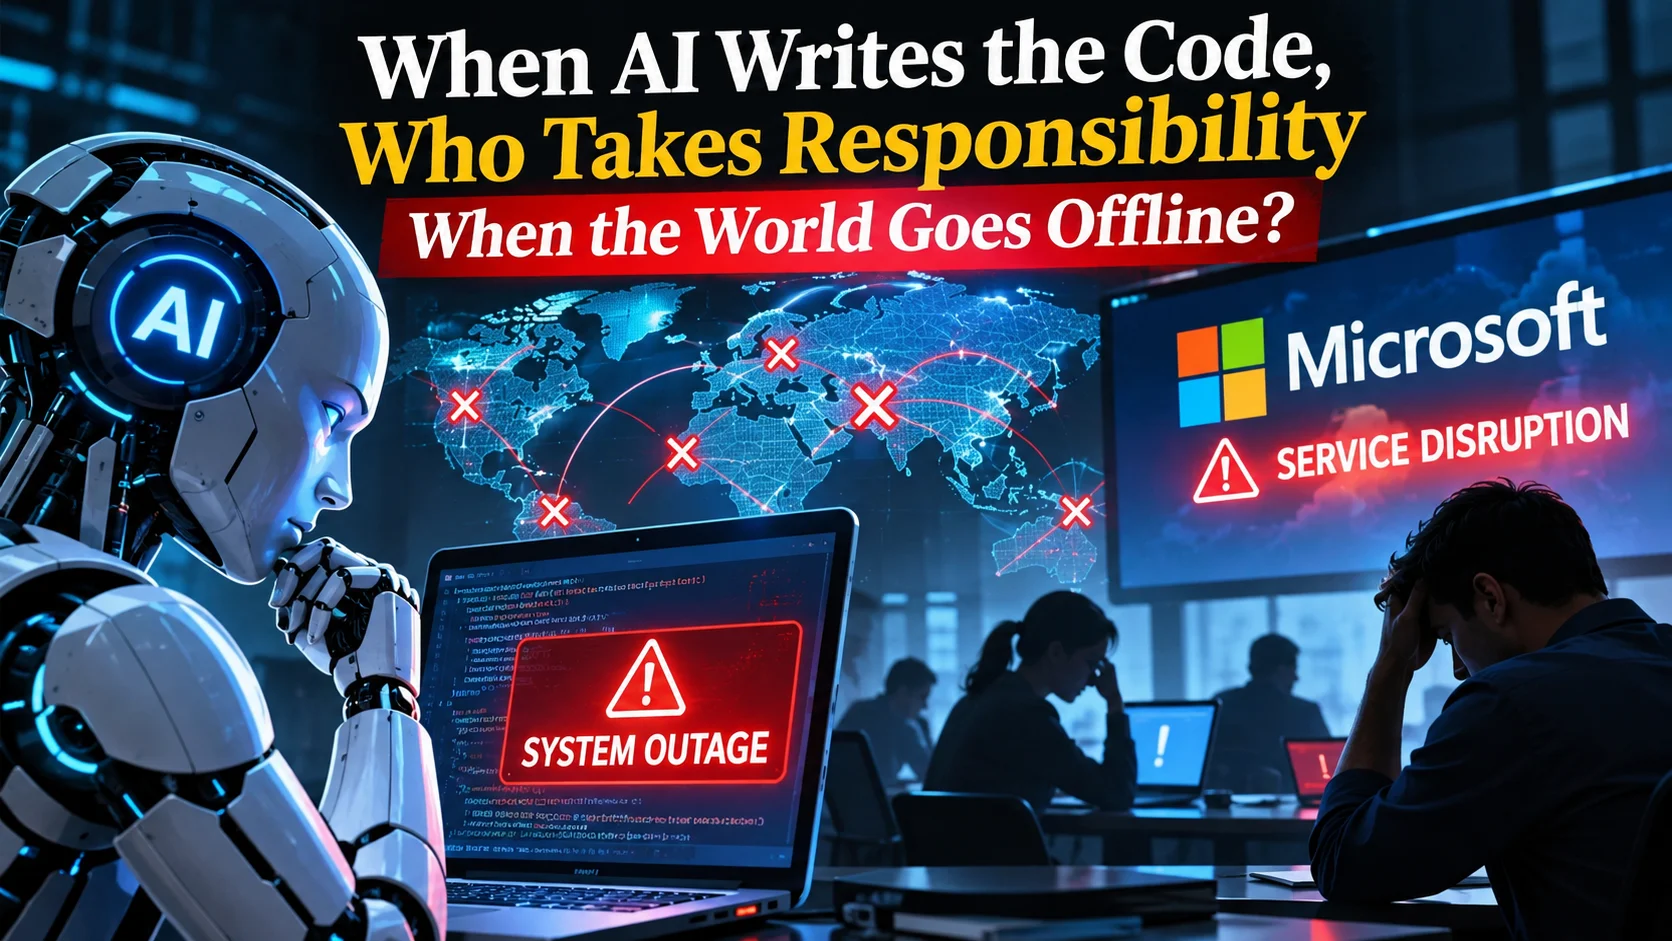
The global disruption of Microsoft’s services on November 12 and 13, 2026, has brought an important question to the forefront of the technology debate: what happens when the systems responsible for keeping the digital world running become vulnerable to errors introduced by increasingly autonomous artificial intelligence? Millions of users depend on Microsoft for email, communication, document management, cloud storage, cybersecurity and business operations. When these services experienced widespread disruption, the consequences extended well beyond people being unable to access their Outlook accounts. Businesses faced communication difficulties, organisations struggled with their routine operations, and users discovered how deeply their professional and personal lives had become connected to a handful of technology platforms. While Microsoft has not established that artificial intelligence played any role in the incident, the outage presents an opportunity to examine a growing concern within the technology industry: whether the rapid adoption of AI-assisted software development is introducing new risks into infrastructure that is already extraordinarily complex and interconnected.
The incident also demonstrates the extent to which modern society has concentrated its digital dependence in the hands of a relatively small number of technology companies. Microsoft is no longer simply a software company providing operating systems and office applications. Its cloud infrastructure supports businesses, government departments, financial institutions, educational organisations and countless other services across the world. Microsoft 365, Azure and the company’s wider cloud ecosystem have become essential components of everyday economic activity. An interruption in these services can therefore affect organisations that have no direct connection with one another but happen to depend on the same underlying technology. Outlook, Teams, SharePoint and Copilot may appear to be separate products to customers, yet their operations involve overlapping infrastructure, identity services, networking systems and cloud resources. When a common component experiences a serious failure, the impact can travel across multiple applications. This interconnectedness is one of the principal advantages of cloud computing, but it also creates the possibility that a relatively limited technical problem could develop into a widespread disruption.
Microsoft’s incident updates indicated that servers had unexpectedly become unavailable, while automated health checks and recovery processes encountered difficulties. The company also investigated a network configuration change and took corrective measures, including attempts to reverse the change. However, the precise technical cause had not been conclusively established in the public reporting available on November 13. This distinction matters because the immediate temptation in an era dominated by artificial intelligence is to connect every major technology failure with AI. There is currently no confirmed evidence that an AI coding agent generated the faulty configuration, that an AI system authorised its deployment or that AI-assisted programming was responsible for the disruption. Nevertheless, the possibility deserves examination because the methods through which software is written, tested and deployed are undergoing a fundamental transformation. The traditional boundaries between human programming, automated testing and machine-led infrastructure management are becoming increasingly blurred, and the consequences of mistakes in these environments can be far more serious than those associated with ordinary software applications.
Artificial intelligence has moved considerably beyond suggesting lines of code or helping programmers correct minor errors. Modern AI systems can examine large codebases, generate entire software components, modify existing applications, execute development commands, run tests and participate in deployment workflows. In some environments, developers can describe a desired outcome in ordinary language and allow an AI agent to undertake much of the programming required to achieve it. This approach, popularly described as vibe coding, has made software development accessible to people who may not possess extensive programming knowledge. It has also enabled experienced developers to complete routine tasks much faster. A business can now develop a prototype, automate an internal process or build an application in a fraction of the time that would previously have been required. These developments represent a genuine technological breakthrough, but they also create a difficult question about the reliability of code that is generated at extraordinary speed and subsequently incorporated into critical systems.
The central concern is not that artificial intelligence is incapable of writing good software. In many circumstances, AI-generated code can be efficient, technically sound and even superior to code produced manually. The problem is that technically correct code is not necessarily operationally safe. A piece of software may perform exactly as intended under controlled testing conditions but behave unexpectedly when exposed to millions of users, unusual network conditions or interactions with other components. An AI system may understand the immediate programming requirement without having complete knowledge of the infrastructure in which the resulting code will operate. It may recommend a modification that improves one particular process while unintentionally affecting another. It may also overlook a dependency that is not visible in the portion of the codebase it has examined. Such mistakes are not exclusive to artificial intelligence; human engineers have made similar errors throughout the history of computing. However, the speed and scale at which AI systems can generate and modify software introduce a different dimension to the problem.
Consider a hypothetical situation in which an AI coding agent is instructed to improve the performance of a cloud network. The agent examines the existing configuration and proposes modifications to how traffic is distributed between servers. Its recommendations pass routine validation and appear successful in a controlled environment. However, an overlooked dependency causes a monitoring component to misidentify certain healthy servers as unavailable. Traffic is consequently redirected towards the remaining servers, increasing their workloads. As the pressure rises, additional servers become unresponsive, creating a cascading failure. This is not an explanation of Microsoft’s November outage, nor is there evidence that such a sequence occurred. It is an illustration of how an apparently minor software or configuration error could potentially produce consequences across a large infrastructure. The danger becomes particularly significant when an automated system is given the authority not only to recommend changes but also to implement them without independent verification.
This is where the growing popularity of autonomous coding agents deserves particular attention. Earlier generations of programming assistants generally operated as tools that suggested code while leaving the developer responsible for incorporating and deploying it. Newer systems can perform multiple stages of the development process, including examining existing files, making modifications, executing tests and correcting errors. The next stage of this evolution is the integration of such agents into production engineering workflows, where they may be permitted to make changes to live systems. For organisations looking to reduce costs and accelerate development, the attraction is obvious. An AI agent can work continuously, process enormous amounts of information and undertake repetitive engineering tasks without the limitations of conventional working hours. Yet the same capability can become a source of risk if the system is given more authority than its reliability and understanding justify.
Traditional software development involves several layers of responsibility. Requirements are defined, solutions are designed, programmers write code, reviewers examine modifications, testing teams evaluate performance and authorised personnel approve deployment. These processes are not always perfect, but they provide opportunities to identify mistakes before they reach production. AI-assisted development can compress several of these stages. A developer may describe a problem, receive a proposed solution, ask the AI to modify it and deploy the result in a relatively short period. The productivity advantage is substantial, but the danger lies in allowing the review process to shrink at the same rate as development time. When an AI agent generates thousands of lines of code or modifies several interconnected components, a human reviewer may find it difficult to verify every assumption. There is also a psychological tendency to place excessive confidence in outputs that appear technically sophisticated, particularly when automated tests indicate that the proposed changes have been successful. However, automated tests can only establish that a system has performed correctly under the conditions they examine. They cannot guarantee that every possible operational consequence has been anticipated.
The risks become even greater when AI systems are involved in managing infrastructure rather than merely developing applications. A faulty mobile application may inconvenience its users, but an incorrect change to authentication, networking, server management or resource allocation can affect multiple services simultaneously. Cloud infrastructure is built around shared components, and modifications to those components can have consequences far beyond the original task. An AI agent asked to optimise a particular process may unintentionally alter the behaviour of a common service on which several other applications depend. If the change is deployed across multiple regions, the consequences could become international before engineers have sufficient time to understand what has happened. This is why the distinction between using AI to write an application and allowing AI to modify the infrastructure supporting thousands of applications is so important. The latter requires substantially stronger safeguards.
The technology industry has already witnessed incidents demonstrating how software changes can produce consequences on a global scale. The CrowdStrike incident of July 2024 is an important example. A defective content update in CrowdStrike’s Falcon security software caused widespread Windows system crashes, affecting airlines, hospitals, financial institutions and businesses across different countries. The incident was not caused by artificial intelligence, and its technical circumstances were different from those surrounding Microsoft’s November 2026 disruption. Nevertheless, it demonstrated how a change distributed across a large number of interconnected systems can create a major operational crisis. It also exposed the importance of controlled deployment, independent testing and the ability to reverse faulty updates quickly. As AI systems become increasingly involved in generating and modifying software, these lessons become even more relevant. The industry must ensure that the speed of deployment does not exceed the ability to detect and contain errors.
Another important concern is the possibility of automated systems amplifying their own mistakes. Imagine a cloud provider using several AI agents to monitor servers, optimise network traffic and resolve operational problems. One agent identifies what it believes to be a capacity issue and recommends a change. Another agent implements the modification, while a third responds to the resulting system behaviour by restarting affected services. If the initial decision was based on incomplete information, the subsequent automated responses may make the situation more complicated. One system may attempt to restore capacity while another reduces traffic or changes resource allocation. The problem is no longer limited to an individual programming error; it becomes a situation in which multiple automated systems are responding to one another without necessarily sharing a complete understanding of the underlying failure. Such scenarios are hypothetical, but they underline the importance of designing AI-driven infrastructure with clearly defined permissions, independent monitoring and reliable mechanisms for human intervention.
There is also a fundamental question about whether an AI system can fully understand the consequences of the code it generates. Modern models can analyse programming languages, identify patterns, explain functions and produce solutions to sophisticated technical problems. Some can examine large software projects and recognise relationships between different components. However, generating code that satisfies a particular instruction is not the same as possessing complete operational knowledge of the environment in which that code will function. A cloud platform is not simply a collection of programming instructions. It is a constantly changing ecosystem involving physical hardware, network connections, user behaviour, security systems, databases, legacy software and external dependencies. Even an experienced engineer may not have complete knowledge of every interaction within such an environment. An AI system working with limited context may be even less equipped to anticipate unusual consequences. The industry must therefore avoid treating confidence in an AI-generated solution as proof of its reliability.
The question of responsibility is equally important. If an AI agent generates code that causes a major infrastructure failure, who should be held accountable? Can the software developer argue that the code was written by artificial intelligence? Can the company claim that the AI system made an independent decision? Can the technology provider be held responsible simply because its model generated the faulty instructions? These questions will become increasingly relevant as AI agents gain greater access to business systems and production environments. An AI model cannot simply be treated as an independent legal entity to which an organisation can transfer its responsibilities. The organisation that deploys the technology remains responsible for the manner in which it is used, the permissions it receives and the safeguards established around its decisions. If a company allows an AI agent to modify critical infrastructure, it must have a clear understanding of the risks and establish procedures that prevent unauthorised or inadequately tested changes from reaching production.
The technology industry should therefore begin adopting a more rigorous framework for AI-assisted engineering. AI-generated code should be subject to meaningful review, particularly when it affects security, networking, authentication or infrastructure management. Automated testing should include not only routine performance checks but also stress testing, failure simulations and assessments of how modifications interact with dependent services. Changes should be deployed gradually rather than distributed simultaneously across an entire global network. Organisations should maintain reliable rollback mechanisms so that a faulty modification can be reversed without introducing further instability. AI agents should also operate with restricted permissions, receiving only the access necessary to perform their assigned tasks. Most importantly, systems responsible for monitoring and authorising critical infrastructure changes should be sufficiently independent to identify problems even when the AI agent responsible for making those changes reports that everything is functioning correctly.
Human approval should remain an essential component of high-risk engineering decisions. This does not mean that every minor software modification should require a lengthy manual approval process. Such an approach would undermine the productivity advantages that make AI useful in the first place. Instead, organisations should classify software changes according to their potential impact. A minor alteration to the appearance of a website can reasonably pass through an automated deployment process after standard testing. A change to global network routing, authentication infrastructure, server health monitoring or data management should face a substantially higher level of scrutiny. An independent engineer should be able to examine and approve such modifications before they are implemented. The principle should be straightforward: the greater the authority given to an AI system, the stronger the verification and accountability mechanisms surrounding it must be.
For governments and businesses, the Microsoft disruption also raises questions about continuity planning. Organisations have increasingly moved their email, documents, customer information, internal communication and business applications onto cloud platforms. While this arrangement offers significant advantages, it can also create a dangerous dependence on a single provider. Critical organisations should consider whether they have adequate alternative communication arrangements, data recovery procedures and operational continuity plans when essential cloud services become unavailable. This is particularly important for healthcare institutions, financial organisations, emergency services and government departments, where an interruption can have consequences beyond lost productivity. AI adoption should not distract organisations from the more fundamental responsibility of ensuring that essential services can continue operating when technology fails.
The larger issue is that the world is moving towards a form of software development in which humans increasingly describe objectives while machines perform much of the technical work. This transition may eventually change the nature of programming itself. Developers may spend less time writing individual lines of code and more time defining requirements, supervising AI agents, evaluating outputs and managing complex systems. This is not necessarily a negative development. AI has the potential to improve software quality, identify vulnerabilities more quickly and make technology development more accessible. It can also assist engineers in detecting problems that might otherwise remain unnoticed. But these advantages will be sustainable only if organisations understand that AI is a tool whose capabilities must be matched by appropriate controls.
The Microsoft outage should not be used as evidence that artificial intelligence is already responsible for bringing down global technology infrastructure. Such a conclusion would be premature and unsupported. The definitive cause of the incident must emerge from Microsoft’s technical investigation, and any assessment of AI involvement must be based on verifiable evidence rather than speculation. However, the incident has brought attention to a question that the technology industry cannot afford to ignore. As AI systems become more deeply involved in writing software, managing networks and controlling cloud infrastructure, the consequences of their mistakes could extend far beyond the organisations that deploy them. The next major infrastructure failure may involve an AI-generated modification, or it may result from an entirely conventional human error. In either case, the underlying requirement remains the same: critical technology systems must be designed to withstand mistakes, identify failures quickly and recover without allowing one defect to bring down an entire network.
Ultimately, the real debate is not whether artificial intelligence should be allowed to write code. That transition is already underway and is likely to accelerate. The more important question is whether the technology industry is developing the necessary systems of accountability at the same speed as it is developing AI capabilities. There is a danger in measuring technological progress only by the amount of software that can be produced, the number of programmers who can be replaced or the time saved during development. In critical infrastructure, reliability is just as important as efficiency. A system that can produce software ten times faster but substantially increases the possibility of an uncontrolled failure cannot automatically be considered an improvement.
The future will almost certainly belong to AI-assisted engineering, but that future must not be built on the assumption that machines are incapable of making consequential mistakes. Microsoft’s latest disruption offers an opportunity to reconsider the relationship between automation, human oversight and the infrastructure on which modern society depends. When the next major outage occurs, the most important question may not simply be which server failed or which configuration went wrong. It may be whether the change was generated by an AI system, who authorised its deployment, whether it was independently tested and whether anyone had the power to stop it before the consequences spread. Artificial intelligence may increasingly write the code that keeps the digital world functioning, but responsibility for ensuring that the world does not go offline must remain firmly human.